How I Set Up Private and Residential Proxies Behind One Relay
Updated · 8 min read
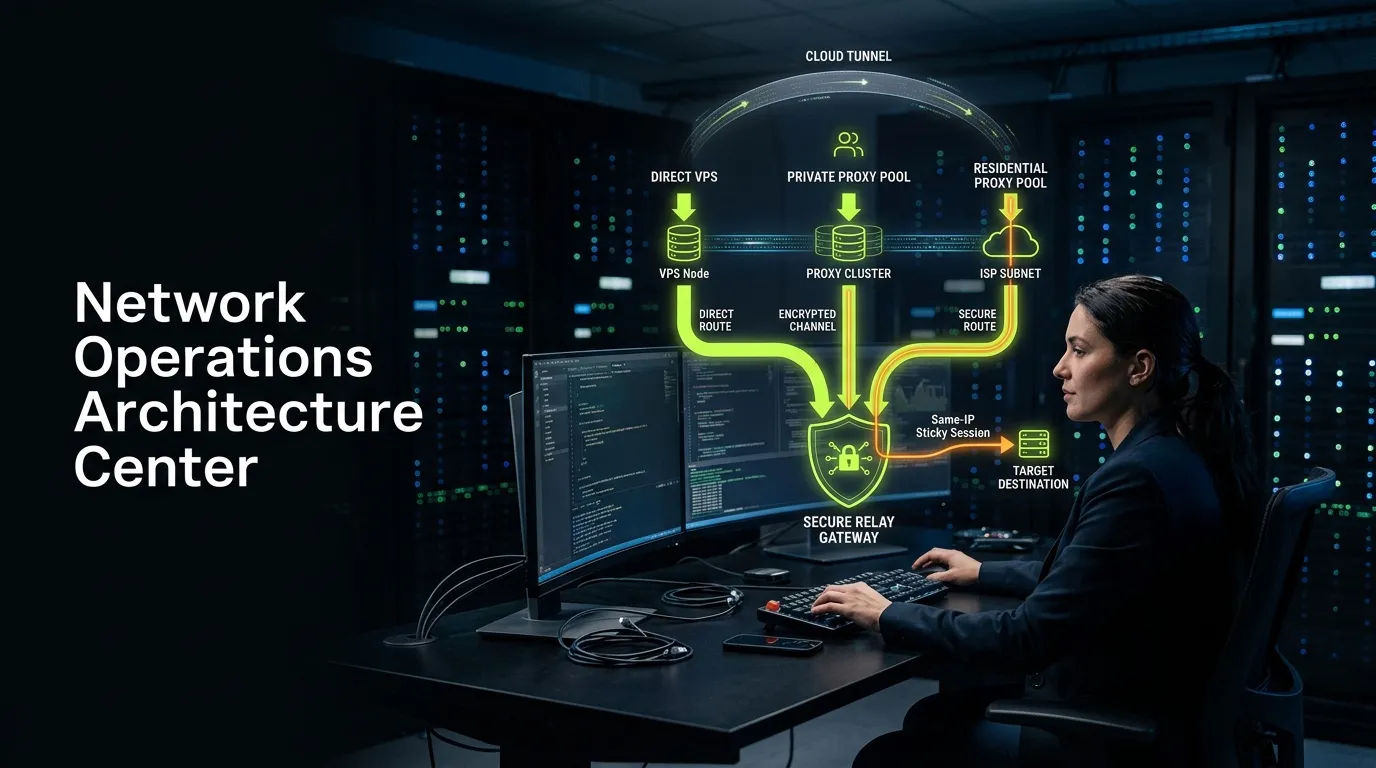
Problem Agents and backend jobs needed direct, private, residential or browser egress without proxy credentials scattered across every script.
Solution
One authenticated HTTPS relay on a VPS with three egress levels, optional Browserless rendering, and sticky session keys when a workflow needs the same IP across requests. Clients get a clean API while proxy credentials, retries and provider quirks stay inside one controlled box.
A practical, public-safe walkthrough of the proxy relay pattern: one HTTPS endpoint, three egress levels, Browserless rendering when JavaScript matters, and sticky sessions when a workflow needs the same IP across requests.
I wanted one place where my agents and backend jobs could make outbound web requests without scattering proxy credentials across every script. Sometimes I need the speed of direct VPS egress. Sometimes I need a private proxy. Sometimes I need residential egress. Sometimes I need a real browser. The solution was a small authenticated relay running on a VPS.
One public API, multiple egress choices, zero proxy credentials in client code.
This post explains the setup without publishing any live credentials or provider-specific customer IDs. Use the placeholders as a blueprint for your own deployment.
What the relay does
The relay accepts an authenticated HTTPS request, chooses an egress route based on a level parameter, and then fetches or renders the target URL. The public API stays deliberately small:
GET  /health
GET  /fetch?url=<target>&level=<0|1|2>
POST /browse
POST /function?token=<browserless-token>| Route | What it does | Best for |
|---|---|---|
/fetch |
Uses Python HTTP requests through direct/private/residential egress | Fast HTML, JSON APIs, simple pages |
/browse |
Uses Browserless/Chrome through the same egress tiers | JavaScript pages, SPA content, click/scroll workflows |
/function |
Passes raw Browserless v2 function calls to a local Browserless container | External agents that already know Browserless v2 |
/health |
Reports loaded pool counts and Browserless status | Monitoring and sanity checks |
Architecture
Client, Worker, or AI agent
        ↓ HTTPS + auth
Cloudflare edge
        ↓ Cloudflare Tunnel
VPS relay on 127.0.0.1
        ↓ chooses route per request
level=0  direct VPS egress
level=1  private proxy pool
level=2  residential proxy pool
        ↓ optional Browserless Chrome
Target website
The tunnel matters because the relay can stay bound to localhost. No proxy service needs to listen on a public port. Cloudflare handles TLS, DNS, and the tunnel from the edge back into the VPS.
Security boundary. Treat the relay as private infrastructure. Require an auth token, keep upstream proxy credentials only on the VPS, and never expose raw proxy username/password pairs to Workers, browser clients, or agent prompts.
Proxy pool files
The relay loads two local files on startup: one for private proxies and one for residential proxies. Each non-comment line uses this neutral shape:
host:port:username:passwordExample placeholders:
# private_proxies.txt
private-gateway.example.net:8000:PRIVATE_USER_001:PRIVATE_PASSWORD
private-gateway.example.net:8000:PRIVATE_USER_002:PRIVATE_PASSWORD

# residential_proxies.txt
res-gateway.example.net:22225:RES_USER_SESSION_001:RES_PASSWORD
res-gateway.example.net:22225:RES_USER_SESSION_002:RES_PASSWORD
res-gateway.example.net:22225:RES_USER_SESSION_003:RES_PASSWORD
Level selection is then just a request parameter:
| Level | Alias | Egress route | Use when |
|---|---|---|---|
0 |
direct, vps, none |
No upstream proxy | You want speed and the target tolerates VPS traffic |
1 |
private, priv |
Random private proxy entry | You want a stable datacenter/private IP pool |
2 |
residential, res |
Random residential proxy entry | You need residential-looking traffic or stricter target compatibility |
The relay logic
The relay loads the proxy files into memory and converts each line into a proxy URL that Python requests can use:
def load_proxy_file(path):
    proxies = []
    with open(path) as f:
        for line in f:
            line = line.strip()
            if not line or line.startswith('#'):
                continue
            host, port, user, pwd = line.split(':', 3)
            proxies.append(f'http://{user}:{pwd}@{host}:{port}')
    return proxies
Then the request chooses a level:
def parse_level(raw):
    value = (raw or '').strip().lower()
    if value in ('', '0', 'default', 'direct', 'vps', 'none'):
        return 'direct'
    if value in ('1', 'private', 'priv'):
        return 'private'
    if value in ('2', 'residential', 'resident', 'res'):
        return 'residential'
    return None
The important production detail is that direct mode should not inherit any proxy environment variables from the host. Use a fresh requests session and disable trust in environment proxy variables:
def make_session():
    session = requests.Session()
    session.trust_env = False
    return session
Sticky sessions for same-IP continuity
Random proxy rotation is useful for broad scraping. But login flows, carts, multi-page crawls, and stateful browser sessions often need the same IP across several requests. For that, the relay supports a sticky session key:
session=user-123The same session string maps to the same proxy-list index every time:
import hashlib

def choose_proxy_from_pool(proxy_pool, sticky_session=None):
    if sticky_session:
        digest = hashlib.sha256(sticky_session.encode('utf-8')).digest()
        index = int.from_bytes(digest[:8], 'big') % len(proxy_pool)
        return proxy_pool[index], index
    return random.choice(proxy_pool), None
This is intentionally stateless. There is no database to maintain and no in-memory session table to lose on restart. As long as the proxy file order stays the same, the same key maps to the same upstream proxy entry.
| Parameter | Meaning |
|---|---|
session |
Preferred sticky-session key |
sid |
Short alias |
sticky_session |
Descriptive alias |
proxy_session |
Explicit proxy-session alias |
Provider nuance. For fixed private proxies, sticky mapping means the same private IP. For residential providers, it means the same provider session credential line. The residential network should keep the same exit IP for that provider session’s lifetime, but the provider can still expire or rotate sessions according to its own rules.
Raw HTTP use cases with /fetch
Fast direct request
curl -H "X-Auth-Token: YOUR_RELAY_TOKEN" "https://proxy.yourdomain.com/fetch?url=https://example.com&level=0"Use direct mode for low-friction pages, your own APIs, public metadata, or targets where a VPS IP is fine.
Private proxy request
curl -H "X-Auth-Token: YOUR_RELAY_TOKEN" "https://proxy.yourdomain.com/fetch?url=https://httpbin.org/ip&level=1"Use private proxies when you want a non-VPS egress pool but do not need residential traffic. Private proxies are usually faster and cheaper than residential routes.
Residential request
curl -H "X-Auth-Token: YOUR_RELAY_TOKEN" "https://proxy.yourdomain.com/fetch?url=https://httpbin.org/ip&level=2"Use residential egress for stricter targets, geo-sensitive pages, marketplace pages, and flows where residential traffic behaves more like a real user connection.
Same session, same IP
curl -H "X-Auth-Token: YOUR_RELAY_TOKEN" "https://proxy.yourdomain.com/fetch?url=https://httpbin.org/ip&level=2&session=account-42"Repeat the same request with the same session and the relay chooses the same proxy-list entry. Use a different session value for a different sticky route.
Browser use cases with /browse
Some pages do not reveal useful data from a raw HTTP fetch. They need JavaScript, cookies, XHR listeners, scrolling, or a real DOM. That is where Browserless comes in.
curl -X POST "https://proxy.yourdomain.com/browse"   -H "X-Auth-Token: YOUR_RELAY_TOKEN"   -H "Content-Type: application/json"   --data '{
    "url": "https://example.com",
    "level": "2",
    "session": "browser-job-abc",
    "wait_until": "domcontentloaded",
    "timeout": 60
  }'
The relay chooses the same level and sticky session logic, then launches Browserless with the selected upstream proxy. This means /fetch and /browse can share the same session key when a workflow moves from API fetches to browser rendering.
For custom extraction, pass a trusted script body:
curl -X POST "https://proxy.yourdomain.com/browse"   -H "X-Auth-Token: YOUR_RELAY_TOKEN"   -H "Content-Type: application/json"   --data '{
    "url": "https://example.com",
    "level": "2",
    "session": "research-user-7",
    "script": "await page.goto(context.url, {waitUntil: context.waitUntil, timeout: context.gotoTimeout}); return {data: {title: await page.title()}, type: 'application/json'};"
  }'
Do not expose arbitrary scripts publicly. A Browserless script endpoint can run powerful browser automation. Keep it behind strong auth and only let trusted callers send scripts.
Raw Browserless v2 for agents
Some AI agents already know Browserless v2 and expect a base URL plus token:
Browserless base URL: https://proxy.yourdomain.com
Browserless secret: YOUR_BROWSERLESS_SECRET
Those agents can call:
POST https://proxy.yourdomain.com/function?token=YOUR_BROWSERLESS_TOKENThat route can be a narrow passthrough to a local Browserless v2 container, while the custom /fetch and /browse relay stays available on the same hostname.
Which mode should you use?
| Situation | Endpoint | Level | Session? |
|---|---|---|---|
| Fast public API or simple HTML | /fetch |
0 |
No |
| General scraping with better egress than VPS | /fetch |
1 |
Optional |
| Strict target or residential-only flow | /fetch |
2 |
Usually yes |
| Login, cart, or multi-step workflow | /fetch or /browse |
1 or 2 |
Yes |
| JavaScript-rendered page | /browse |
0, 1, or 2 |
Depends on flow |
| Agent already written for Browserless v2 | /function |
Browserless-level config | Handled in agent code |
Operational rules I would keep
- Keep Browserless local-only. Expose it through the relay or tunnel, never as an open public port.
- Use short timeouts. Proxy networks fail. Timeouts and retries are part of the product.
- Strip forwarding headers. Do not forward
X-Forwarded-For,CF-Connecting-IP,X-Real-IP, or similar identity headers to targets. - Separate relay tokens from Browserless tokens. A raw browser automation endpoint is more powerful than a simple fetch endpoint.
- Log route metadata, not secrets. Keep useful headers like
X-Relay-LevelandX-Relay-Sticky-Index, but never log proxy passwords. - Use stable session IDs intentionally. A user ID, account ID, or workflow ID can be a good sticky key. A random UUID per request defeats the point.
The takeaway
The pattern is simple: one authenticated relay, multiple egress levels, optional browser rendering, and sticky session keys when continuity matters. It gives agents and Workers a clean API while keeping the messy parts—proxy credentials, retries, Browserless, and provider quirks—inside one controlled box.
That separation is what makes the system easy to extend. You can add new pools, swap providers, expose a Browserless v2 passthrough, or tune sticky-session behavior without rewriting every client that needs to browse the web.
Questions people ask
- How do sticky sessions keep the same IP?
- The same session string maps to the same proxy-list index every time, using a SHA-256 hash of the key. It is stateless: as long as the proxy file order stays the same, the same key maps to the same upstream entry.
- Does a residential sticky session guarantee the same exit IP?
- For fixed private proxies it means the same private IP. For residential providers it means the same provider session credential line, and the provider can still expire or rotate sessions according to its own rules.
- What makes a good sticky session key?
- A user ID, account ID or workflow ID. A random UUID per request defeats the point.