Build a Secure VPS Crawl Engine with Proxy Levels and Browserless
Updated · 11 min read
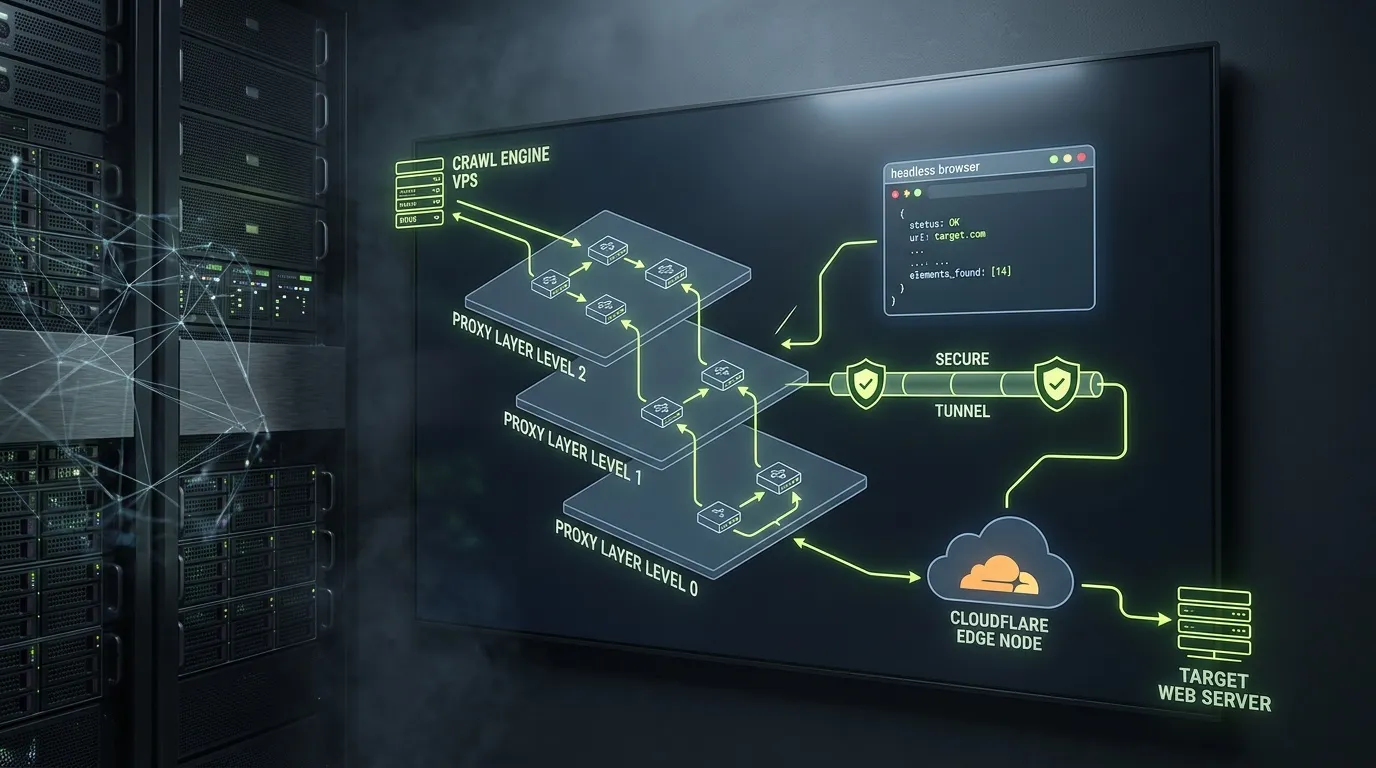
Problem My apps and Workers needed controlled egress and optional browser rendering without becoming a public open proxy.
Solution
Run a private, authenticated relay on a VPS with three proxy levels (direct, private, residential) and Browserless for JavaScript rendering, exposed only through Cloudflare Tunnel. Callers choose a URL, a level and whether to render; the crawl engine handles the rest.
A practical guide for setting up a private crawl engine on a VPS: direct egress, private proxies, residential proxies, JavaScript rendering with Browserless, Cloudflare Tunnel exposure, endpoint security, and Cloudflare Worker integration.
This guide shows how to build a crawl engine that you control. The goal is not to expose a public open proxy. The goal is to create a private, authenticated service that your own apps or Cloudflare Workers can call when they need controlled egress and optional browser rendering.
Put the dangerous parts in one hardened place: proxy credentials, browser rendering, retries, timeouts, and network policy.
What you are building
The final architecture looks like this:
Cloudflare Worker or backend app
        ↓ HTTPS request with X-Auth-Token
Cloudflare edge
        ↓ Cloudflare Tunnel
VPS relay bound to 127.0.0.1
        ↓ chooses route per request
Level 0: direct VPS egress
Level 1: private proxy pool
Level 2: residential proxy pool
        ↓ optionally Browserless Chrome
Target website
The public API stays small:
GET /health
GET /fetch?url=<target>&level=<0|1|2>
GET /browse?url=<target>&level=<0|1|2>| Endpoint | Purpose | Use when |
|---|---|---|
/fetch |
Raw HTTP fetch through a selected egress route | The target returns useful HTML or JSON without JavaScript |
/browse |
Headless Chrome render through a selected egress route | The target requires JavaScript, SPA hydration, or browser behavior |
/health |
Basic service status | Monitoring and sanity checks |
Prepare the VPS
Start with a small Ubuntu VPS. For light crawling and a few browser sessions, 2 CPU cores and 4–8 GB RAM is enough to begin. Browser rendering is the expensive part, so size the server based on how many concurrent Chrome sessions you need.
apt update
apt install -y python3 python3-pip docker.io
systemctl enable --now docker
Create a project directory:
mkdir -p /opt/crawl-engine
cd /opt/crawl-engine
Install Python dependencies. You can use a virtual environment if you prefer; this example keeps the commands short.
pip3 install --break-system-packages flask requests gunicornProduction note. Flask is fine as the app framework, but do not run the Flask development server in production. Run the app under Gunicorn and systemd.
Create proxy pool files
Store your upstream proxies in local files on the VPS. Keep these files private and never publish them. Use placeholder names like this:
/opt/crawl-engine/private_proxies.txt
/opt/crawl-engine/residential_proxies.txt
Each line can use the common format:
host:port:username:passwordExample with fake credentials:
proxy-private.example.net:8000:PRIVATE_USER:PRIVATE_PASSWORD
res-gateway.example.net:22225:RES_USER_SESSION_001:RES_PASSWORD
res-gateway.example.net:22225:RES_USER_SESSION_002:RES_PASSWORD| Level | Pool file | Description |
|---|---|---|
0 |
none | Direct VPS IP, no upstream proxy |
1 |
private_proxies.txt |
Private or datacenter proxy pool |
2 |
residential_proxies.txt |
Residential proxy pool |
Restrict permissions:
chmod 600 /opt/crawl-engine/*_proxies.txtWrite the relay app
Create /opt/crawl-engine/crawl_relay.py. This is a compact reference implementation. It includes authentication, proxy level selection, header stripping, raw fetching, and a Browserless-backed render endpoint.
import os
import random
from urllib.parse import urlencode, urlparse

from flask import Flask, request, Response
import requests

app = Flask(__name__)

PRIVATE_PROXY_FILE = "/opt/crawl-engine/private_proxies.txt"
RESIDENTIAL_PROXY_FILE = "/opt/crawl-engine/residential_proxies.txt"
AUTH_TOKEN = os.environ.get("CONTEXTFORCE_AUTH_TOKEN")
BROWSERLESS_URL = os.environ.get("BROWSERLESS_URL", "http://127.0.0.1:3000")

def load_proxy_file(path):
    proxies = []
    if not os.path.exists(path):
        return proxies
    with open(path) as f:
        for line in f:
            line = line.strip()
            if not line or line.startswith("#"):
                continue
            host, port, user, pwd = line.split(":", 3)
            proxies.append(f"http://{user}:{pwd}@{host}:{port}")
    return proxies

private_proxies = load_proxy_file(PRIVATE_PROXY_FILE)
residential_proxies = load_proxy_file(RESIDENTIAL_PROXY_FILE)

def parse_level(raw):
    value = (raw or "").strip().lower()
    if value in ("", "0", "default", "direct", "vps", "none"):
        return "direct"
    if value in ("1", "private", "priv"):
        return "private"
    if value in ("2", "residential", "resident", "res"):
        return "residential"
    return None

def check_auth():
    token = request.headers.get("X-Auth-Token", "") or request.args.get("token", "")
    return bool(AUTH_TOKEN and token == AUTH_TOKEN)

def make_session():
    session = requests.Session()
    session.trust_env = False
    return session

def choose_proxy(level):
    if level == "direct":
        return None
    if level == "private":
        if not private_proxies:
            raise RuntimeError("No private proxies loaded")
        return random.choice(private_proxies)
    if level == "residential":
        if not residential_proxies:
            raise RuntimeError("No residential proxies loaded")
        return random.choice(residential_proxies)
    raise RuntimeError("Invalid level")

def clean_headers(incoming):
    blocked = {
        "host", "cf-connecting-ip", "cf-ipcountry", "cf-ray", "cf-visitor",
        "cdn-loop", "x-forwarded-for", "x-forwarded-host", "x-forwarded-proto",
        "x-real-ip", "forwarded",
    }
    return {k: v for k, v in incoming if k.lower() not in blocked}

@app.route("/health")
def health():
    return f"OK - direct=vps, private={len(private_proxies)}, residential={len(residential_proxies)}, browserless={BROWSERLESS_URL}"

@app.route("/fetch")
def fetch_raw():
    if not check_auth():
        return Response("Unauthorized", status=401)

    target_url = request.args.get("url")
    if not target_url:
        return Response("Missing url", status=400)

    level = parse_level(request.args.get("level"))
    if level is None:
        return Response("Invalid level", status=400)

    try:
        timeout = min(int(request.args.get("timeout", "15")), 30)
        attempts = min(int(request.args.get("attempts", "3")), 10)
    except ValueError:
        return Response("Invalid timeout or attempts", status=400)

    if level == "direct":
        attempts = 1

    headers = clean_headers(request.headers)
    session = make_session()
    last_error = "Request failed"

    for _ in range(attempts):
        proxy_url = choose_proxy(level)
        proxy_dict = {"http": proxy_url, "https": proxy_url} if proxy_url else {}
        try:
            resp = session.get(target_url, headers=headers, proxies=proxy_dict, timeout=timeout, allow_redirects=True)
            excluded = {"transfer-encoding", "connection", "keep-alive"}
            out_headers = [(k, v) for k, v in resp.headers.items() if k.lower() not in excluded]
            out_headers.append(("X-Relay-Level", level))
            return Response(resp.content, status=resp.status_code, headers=out_headers)
        except requests.exceptions.Timeout:
            last_error = "Upstream timeout"
        except requests.exceptions.ProxyError:
            last_error = "Proxy error"
        except Exception as e:
            last_error = f"Error: {e}"
            break

    return Response(last_error, status=502)

@app.route("/browse")
def browse():
    if not check_auth():
        return Response("Unauthorized", status=401)

    target_url = request.args.get("url")
    if not target_url:
        return Response("Missing url", status=400)

    level = parse_level(request.args.get("level"))
    if level is None:
        return Response("Invalid level", status=400)

    wait_until = request.args.get("wait_until", "domcontentloaded")
    if wait_until not in {"load", "domcontentloaded", "networkidle0", "networkidle2"}:
        return Response("Invalid wait_until", status=400)

    wait_ms = min(int(request.args.get("wait", "0")), 10000)
    timeout = min(int(request.args.get("timeout", "60")), 120)

    proxy_url = choose_proxy(level)
    launch_query = {}
    proxy_auth = None

    if proxy_url:
        parsed = urlparse(proxy_url)
        launch_query["--proxy-server"] = f"{parsed.scheme}://{parsed.hostname}:{parsed.port}"
        proxy_auth = {"username": parsed.username or "", "password": parsed.password or ""}

    code = """
module.exports = async ({ page, context }) => {
  if (context.proxyAuth) await page.authenticate(context.proxyAuth);
  await page.goto(context.url, { waitUntil: context.waitUntil, timeout: context.gotoTimeout });
  if (context.waitMs > 0) await page.waitForTimeout(context.waitMs);
  return { data: await page.content(), type: 'text/html' };
};
"""

    endpoint = f"{BROWSERLESS_URL.rstrip('/')}/function"
    if launch_query:
        endpoint += "?" + urlencode(launch_query)

    context = {
        "url": target_url,
        "waitUntil": wait_until,
        "waitMs": wait_ms,
        "gotoTimeout": max(timeout - 5, 10) * 1000,
        "proxyAuth": proxy_auth,
    }

    try:
        resp = make_session().post(endpoint, json={"code": code, "context": context}, timeout=timeout)
    except requests.exceptions.ConnectionError:
        return Response("Browserless unavailable", status=503)
    except requests.exceptions.Timeout:
        return Response("Browserless timeout", status=504)

    out_headers = [(k, v) for k, v in resp.headers.items() if k.lower() not in {"transfer-encoding", "connection", "keep-alive"}]
    out_headers.append(("X-Relay-Level", level))
    return Response(resp.content, status=resp.status_code, headers=out_headers)
Important. This compact example shows the shape of the service. For production, add the SSRF protection described later in this guide before exposing it to any caller you do not fully control.
Add Browserless for JavaScript rendering
Run Browserless locally. Do not expose it directly to the internet.
docker run -d \
  --name browserless \
  --restart unless-stopped \
  -p 127.0.0.1:3000:3000 \
  --shm-size=1gb \
  -e MAX_CONCURRENT_SESSIONS=5 \
  browserless/chrome:latest
Keep the concurrency small at first. Chrome is CPU and memory heavy. On a 2-core VPS, start with about five sessions and increase only after watching CPU, memory, and response times.
The relay sends Chrome proxy settings per request. For authenticated proxies, it passes the proxy server as a Chrome flag and then authenticates inside the Browserless function.
Run the relay with systemd and Gunicorn
Generate a long random auth token:
python3 - <<'PY'
import secrets
print(secrets.token_urlsafe(32))
PY
Create /etc/systemd/system/crawl-relay.service:
[Unit]
Description=Secure VPS Crawl Relay
After=network-online.target
Wants=network-online.target

[Service]
Type=simple
User=root
WorkingDirectory=/opt/crawl-engine
Environment=CONTEXTFORCE_AUTH_TOKEN=YOUR_RANDOM_TOKEN
Environment=BROWSERLESS_URL=http://127.0.0.1:3000
ExecStart=/usr/local/bin/gunicorn --workers 4 --worker-class gthread --threads 20 --bind 127.0.0.1:8888 --timeout 90 --graceful-timeout 30 --keep-alive 5 --access-logfile - --error-logfile - crawl_relay:app
Restart=always
RestartSec=5

[Install]
WantedBy=multi-user.target
Start it:
systemctl daemon-reload
systemctl enable --now crawl-relay.service
systemctl status crawl-relay.service
Test locally:
curl http://127.0.0.1:8888/healthExpose it with Cloudflare Tunnel
The relay should stay bound to 127.0.0.1. Use Cloudflare Tunnel to publish a hostname without opening port 8888 on the VPS firewall.
Example tunnel ingress:
ingress:
  - hostname: proxy.example.com
    service: http://127.0.0.1:8888
  - service: http_status:404
Restart the tunnel:
systemctl restart cloudflaredThen test the public hostname:
curl https://proxy.example.com/healthThe secure shape is:
Internet → Cloudflare → Tunnel → 127.0.0.1:8888Avoid this:
Internet → VPS_PUBLIC_IP:8888Test all three proxy levels
Export your token locally while testing:
export CONTEXTFORCE_AUTH_TOKEN='your-token-here'Direct VPS route:
curl -H "X-Auth-Token: $CONTEXTFORCE_AUTH_TOKEN" \
  "https://proxy.example.com/fetch?url=https://httpbin.org/ip&level=0"
Private proxy route:
curl -H "X-Auth-Token: $CONTEXTFORCE_AUTH_TOKEN" \
  "https://proxy.example.com/fetch?url=https://httpbin.org/ip&level=1"
Residential route:
curl -H "X-Auth-Token: $CONTEXTFORCE_AUTH_TOKEN" \
  "https://proxy.example.com/fetch?url=https://httpbin.org/ip&level=2"
The returned IP should change based on the selected route. Then test browser rendering:
curl -H "X-Auth-Token: $CONTEXTFORCE_AUTH_TOKEN" \
  "https://proxy.example.com/browse?url=https://example.com&level=2"
How to secure the endpoint
A crawl relay can become an open proxy if you are careless. Harden it before sharing it with any application.
1. Require a token
Require X-Auth-Token on every expensive route. Avoid putting tokens in query strings because URLs often land in logs.
curl -H "X-Auth-Token: $CONTEXTFORCE_AUTH_TOKEN" \
  "https://proxy.example.com/fetch?url=https://example.com&level=2"
2. Add SSRF protection
Do not let arbitrary callers fetch internal addresses such as 127.0.0.1, private network IPs, or cloud metadata services.
import ipaddress
import socket
from urllib.parse import urlparse

BLOCKED_NETS = [
    ipaddress.ip_network("127.0.0.0/8"),
    ipaddress.ip_network("10.0.0.0/8"),
    ipaddress.ip_network("172.16.0.0/12"),
    ipaddress.ip_network("192.168.0.0/16"),
    ipaddress.ip_network("169.254.0.0/16"),
    ipaddress.ip_network("::1/128"),
    ipaddress.ip_network("fc00::/7"),
    ipaddress.ip_network("fe80::/10"),
]

def validate_target_url(url):
    parsed = urlparse(url)
    if parsed.scheme not in ("http", "https"):
        raise ValueError("Only http and https are allowed")
    if not parsed.hostname:
        raise ValueError("Missing hostname")

    infos = socket.getaddrinfo(parsed.hostname, parsed.port or 443)
    for info in infos:
        ip = ipaddress.ip_address(info[4][0])
        if any(ip in net for net in BLOCKED_NETS):
            raise ValueError("Blocked private/internal target")
Call validate_target_url(target_url) before both /fetch and /browse. If your callers are untrusted, an allowlist is even better than a blocklist.
3. Strip forwarding headers
Do not forward Cloudflare or client identity headers to the target. Strip CF-Connecting-IP, X-Forwarded-For, X-Real-IP, Forwarded, and related headers.
4. Rate limit expensive routes
Put stricter limits on /browse than /fetch. Browser rendering is much more expensive than raw HTTP.
- Use Cloudflare WAF or rate limiting rules.
- Cap Browserless concurrency.
- Cap request timeout and retry attempts.
- Consider per-token quotas if multiple systems use the relay.
5. Keep secrets out of responses
Never return upstream proxy usernames, passwords, proxy file paths, or internal credentials in public responses. Debug headers like X-Relay-Level: residential are fine. Debug headers containing a full proxy URL are not.
Connect a Cloudflare Worker
The Worker should store the relay token as a secret:
wrangler secret put CONTEXTFORCE_AUTH_TOKENThen call the crawl engine with the token in a header. Here is a complete Worker example that supports raw fetch by default and browser rendering when render=1.
const RELAY_BASE = 'https://proxy.example.com';

export default {
  async fetch(request, env) {
    const incoming = new URL(request.url);
    const target = incoming.searchParams.get('url');
    const level = incoming.searchParams.get('level') || '2';
    const render = incoming.searchParams.get('render') === '1';

    if (!target) {
      return new Response('Missing url parameter', { status: 400 });
    }

    let targetUrl;
    try {
      targetUrl = new URL(target);
    } catch {
      return new Response('Invalid target URL', { status: 400 });
    }

    if (!['http:', 'https:'].includes(targetUrl.protocol)) {
      return new Response('Only http and https URLs are allowed', { status: 400 });
    }

    // Optional but recommended: enforce your own domain allowlist here.

    const relayPath = render ? '/browse' : '/fetch';
    const relayUrl = new URL(RELAY_BASE + relayPath);
    relayUrl.searchParams.set('url', targetUrl.toString());
    relayUrl.searchParams.set('level', level);

    if (render) {
      relayUrl.searchParams.set('wait_until', 'domcontentloaded');
      relayUrl.searchParams.set('timeout', '60');
    } else {
      relayUrl.searchParams.set('timeout', '15');
      relayUrl.searchParams.set('attempts', '3');
    }

    const res = await fetch(relayUrl, {
      headers: {
        'X-Auth-Token': env.CONTEXTFORCE_AUTH_TOKEN,
        'User-Agent': 'MyCrawler/1.0',
      },
    });

    if (!res.ok) {
      return new Response(`Relay failed: ${res.status} ${await res.text()}`, { status: 502 });
    }

    if (render) {
      return new Response(await res.text(), {
        headers: {
          'Content-Type': 'text/html; charset=utf-8',
          'Cache-Control': 'no-store',
        },
      });
    }

    return new Response(res.body, {
      status: res.status,
      headers: {
        'Content-Type': res.headers.get('Content-Type') || 'application/octet-stream',
        'Cache-Control': 'no-store',
        'X-Relay-Level': res.headers.get('X-Relay-Level') || level,
      },
    });
  },
};
Token boundary. The browser or public client should never receive the relay token. The public caller talks to the Worker. The Worker talks to the private crawl engine.
Final checklist
- Relay binds to
127.0.0.1. - Browserless binds to
127.0.0.1. - Cloudflare Tunnel exposes only the relay hostname.
CONTEXTFORCE_AUTH_TOKENis required on/fetchand/browse.- Proxy credentials live only on the VPS.
- Forwarding headers are stripped.
- SSRF protection blocks internal/private targets.
- Timeouts, attempts, and Browserless concurrency are capped.
- Cloudflare WAF or rate limiting protects expensive routes.
- The Cloudflare Worker stores the relay token as a secret.
Once this is in place, your applications get one simple interface: choose a URL, choose a proxy level, and decide whether the target needs browser rendering. The crawl engine handles the operational complexity behind a private, authenticated endpoint.
Questions people ask
- Which endpoint should I call?
- /fetch for a raw HTTP fetch when the target returns useful HTML or JSON without JavaScript, /browse when it needs JavaScript, SPA hydration or browser behavior, and /health for monitoring.
- Can I run the Flask development server in production?
- No. Flask is fine as the app framework, but run the app under Gunicorn and systemd.
- Should the browser or public client get the relay token?
- Never. The public caller talks to the Worker, and the Worker, which stores the relay token as a secret, talks to the private crawl engine.